Mina and the Story of Words combines local speech recognition with spells whose effects depend on incantation duration. That gives players a timing-sensitive way to manipulate objects while navigating a 3D environment with a controller.
At Osaka Indie Games Summit 2026, held at Kongres Square Grangreen Osaka on October 3 and 4, Latent Entertainment exhibited a solo-developed 3D action game with a split control scheme: a gamepad for movement, a microphone for manipulating the environment.
In Mina and the Story of Words, speaking a spell can summon a rock or move a platform. The more consequential detail is how the game uses the length of an utterance. Sustaining a platform-raising spell changes its result, making vocal timing part of the control system.
Table of Contents (5)
How movement and spoken spells work together
The controller handles navigation through the 3D space. Speech selects objects and triggers changes to the world around the character. This division lets the player position the character while preparing or sustaining a spoken command.
| Input or system | Function in the demo | Practical significance |
|---|---|---|
| Controller | Moves the character through the 3D environment | Spatial navigation remains on conventional controls |
| “Rock” | Summons a rock | A recognized spell creates an object in the world |
| “Eleve” | Moves a platform | Speech controls an environmental mechanism |
| “Eleve—ate” | Raises a platform according to incantation duration | The length of the utterance affects the result |
| Custom speech-recognition engine | Processes microphone input locally | Recognition does not require a cloud service |
New spells are learned by reading guidance within the stages. That gives exploration a second function: it teaches the vocabulary needed to operate the environment. The stage guidance includes “Eleve,” linking a written instruction to the spoken command for moving a rock platform. Players then observe what their incantation does to the object.
Incantation time adds a second input variable
A basic voice command has a discrete result: recognize the word, execute the action. The platform-raising spell adds duration to that process. The word identifies the action; the time spent sustaining it influences the outcome. The developer has filed a patent application relating to this “incantation time” mechanic.
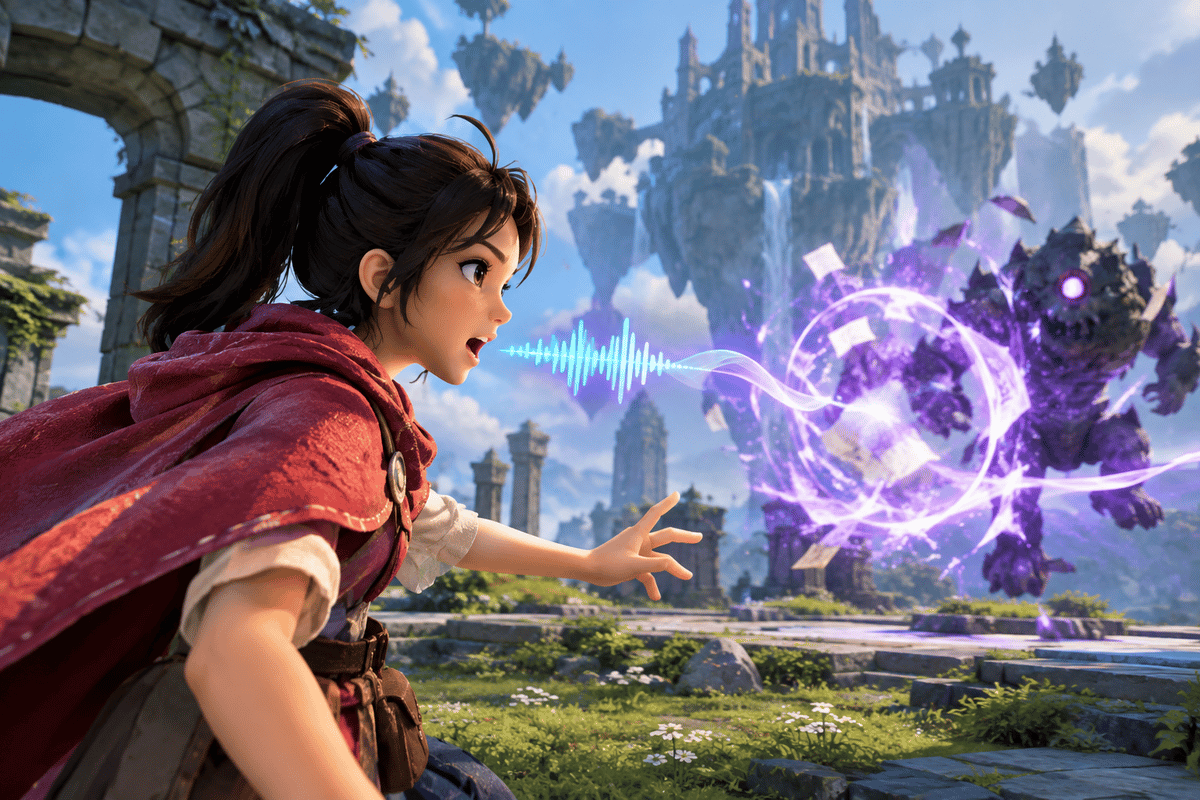
The useful comparison is a charged input—a button held to build up an action before releasing it. Here, the player sustains an incantation instead. A short utterance may produce less platform movement, while a sustained one may raise it farther. In a platform puzzle, that could change whether the next surface is reachable or whether a route becomes usable. The player is managing both position and the extent of an environmental change.
Duration-sensitive input also creates a feedback challenge: recognition and timing are separate things that can go wrong. A missed command could produce no action; a recognized incantation ended too early could produce less movement than intended. Those possibilities call for different corrections—repeat the command in the first case, adjust its duration in the second. For this mechanic, feedback that distinguishes the two would be more useful than a single generic failure signal.
Early spell experiments started from the premise that voice input alone would be slower than controller buttons. The developer’s proposed advantage is the ability to choose among many objects or actions through spoken vocabulary. Incantation duration adds control over the result, giving the microphone a function beyond selecting a command.
Action-focused encounters would place additional pressure on that arrangement. Sustaining a word while moving requires the player to manage speech, timing and positioning simultaneously. The developer is still evaluating whether the game should lean toward puzzles or action. That choice will determine how often players must perform an incantation under pressure.
What local speech recognition changes
Developer yoshi built the speech-recognition engine from scratch over approximately six months. It processes audio locally, without cloud communication for recognition. Spoken commands therefore do not depend on a remote recognition service or its network round trip.
That architecture is relevant to a duration-sensitive mechanic. Cloud recognition would add a network round trip between the player’s speech and its interpretation; local processing removes that particular source of delay. Capturing speech, identifying the command and updating the game state still take time. “Local” describes where recognition happens, not how fast the game responds.
It also limits the need to transmit speech: recognition happens without uploading the utterance to a server. That describes the speech-input path, not a blanket privacy guarantee for every function the finished game might contain.
The developer says the system can work with a small microphone on an ordinary notebook PC and also described headset use. The large microphone at the exhibition is therefore not an inherent requirement. Making the engine operate across devices, including PCs and smartphones, was a technical challenge; those development targets do not define the game’s release platforms.
For this control scheme, useful performance tests would examine repeated recognition of “Rock,” detection of the beginning and end of “Eleve—ate,” and whether similarly timed utterances produce comparable platform movement. Testing those spells with different microphone pickup, pronunciation and background speech would address the actual control demands. Local processing alone does not answer those questions.
Who this control scheme suits
The mechanic’s clearest appeal is to players who enjoy learning environmental rules and adjusting their execution. Reading a spell instruction, trying it on a platform and judging how long to sustain it gives puzzle-minded players more to work with than a voice-activated switch. The attraction is performing the command, not merely replacing a button with a word.
Players looking primarily for fast action face a different tradeoff. Movement stays on the gamepad, but manipulating the environment adds spoken vocabulary and vocal timing to the controls. If sustaining an utterance while steering sounds more distracting than engaging, that distinction matters more than the absence of a cloud connection.
The next development questions
The developer wants to increase the number of summonable items and explore using speech timing to change their properties. Another proposed interaction would trigger changes when the player says two words in sequence. These remain prototype directions, extending the command vocabulary and the information carried by an utterance.
The choice between puzzle-led and action-led design will determine the demands placed on that system. Platform puzzles can give players time to observe and adjust an incantation. Action-heavy sequences would require the same speech input to remain manageable while movement and immediate threats compete for attention. The compelling part is already concrete: the microphone does not just choose a spell—it helps determine what that spell does.
FinalBoss // Gear
Level up your setup
01Top-rated gaming headsetson Amazon→02High-refresh gaming monitorson Amazon→03Gaming chairson Amazon→04Discounted game keyson Kinguin→Affiliate links · As an Amazon Associate, FinalBoss earns from qualifying purchases.
Want to Level Up Your Gaming?
Get access to exclusive strategies, hidden tips, and pro-level insights that we don't share publicly.
Ultimate Tech Strategy Guide + Weekly Pro Tips